“Agent-first” usually means a company where software does the work, which is the least interesting part of it. What agents can do keeps improving on its own, without our help. The question that actually decides whether a business like this holds together is narrower: what does a person still have to look at, and how often?
The useful point is that the bottleneck doesn't disappear when producing work gets cheap. It moves. A business organised around where it moves to is agent-first. A business organised only around the cheap production ends up with an expensive queue.
The bottleneck moves
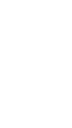
Suppose agents produce work at some rate, a fraction of it needs a person to look before it goes out, and looking takes a while. The capacity of the whole operation is then bounded by:
Human hours divided by how much needs reviewing. How fast the agents work doesn't come into it.
Where \(H\) is the hours a person has, \(f\) is the share of output needing their eyes, and \(t\) is how long each look takes. How fast agents produce work doesn't appear on the right-hand side at all, and that's the whole point. Once producing work has stopped being the bottleneck, making it cheaper again buys you nothing. That leaves three things you can change: the hours, the share and how long each look takes. Hours are the one that can't grow.
This is why “we can generate a thousand of these a day” is rarely the good news it sounds like. If each of those thousand needs four minutes of human judgment, you ship about a hundred and twenty and the other eight hundred and eighty pile up. That backlog isn't a phase you pass through on the way to something better. It's where you stay.
Approve the template, not every result
The first real lever is \(f\), and you don't move it by reviewing faster. You move it by changing what a person is approving.
If someone approves every output one by one, then \(f = 1\) whatever you do, and no amount of speeding up \(t\) will save you. If instead a person approves a kind of output once and agents produce the individual results inside it, then \(f\) drops to how often new kinds appear rather than how often results do. A template, a policy, a set of limits: approval becomes a one-off cost per kind instead of a cost you pay on every single item.
It's the same move as deciding a product is finished: an open-ended commitment turned into a limited one. It fails the same way too, quietly, when new kinds keep getting added because nobody wants to be the person who says no to a reasonable request.
Let programs do the checking
The second lever is \(t\), and the thing to notice is that most review time isn't spent judging anything. It's spent checking: that a claim is true, that a number matches, that a link works, that a name is spelled the way the customer spells it. Checking is the part a person is worst at and least needed for.
Telling a model not to invent facts reduces invented facts. A program that rejects any output containing a fact that isn't in the source removes them. The first is a prompt, the second is code, and only the second lets you stop reading. Anything you can turn into a check should be one, because every check takes a whole category of thing off the list a person has to hold in their head. What's left is judgment: taste, tone, whether this should exist at all. That's where the scarce hours should go.
Make mistakes cheap instead of rare
The third lever is the one people reach for last: lower the stakes instead of raising the accuracy.
How much you review something depends on what a mistake costs. An action you can undo in one click, that reaches one customer instead of ten thousand, that gets staged before it goes live, and that leaves a record of what happened and when, doesn't need the same approval as one you can't take back. You can design for reversibility, and it's usually cheaper to build than the accuracy you'd need to skip the approval without it.
The other half is worth saying plainly. The genuinely irreversible actions stay behind a person forever, however good the agents get: money going out, contracts signed, messages sent to strangers, data deleted. Not because the agent will fail, but because the one time it does, you can't recover, and rare disasters get more likely as volume goes up, not less.
What doesn't get cheaper
None of this helps with the parts of a business that were expensive before agents and still are. Distribution is still rationed: inboxes, app stores and search results have gatekeepers who noticed that producing work got cheap and tightened up accordingly. Trust is still earned slowly and lost quickly. Permission, meaning the legal right to contact someone, hold their data or operate in their market, is still granted by institutions that don't care how the work was made.
And someone is still liable. An agent-first business isn't an unowned one. There has to be a real company, in a real country, that can be invoiced and sued. That requirement clarifies more than it restricts, because it keeps the question honest: not what can be automated, but what you are willing to put your name to a thousand times over.
How we build them at Flits
Flits is a software lab that keeps what it builds. We developed the products here rather than buying them in, which makes the sums above practical rather than theoretical. Every product we add is one more thing that has to keep running without many people behind it, and how many can exist at once is exactly the question above.
So we apply this fairly literally. We approve kinds of thing rather than individual results: a template, a tone of voice, the claims a product is allowed to make, how far a price can move. Agents produce the individual results inside those limits, and do most of the work of keeping a product alive after it ships. Anything a program can check gets checked that way, and the program decides rather than a person reading the result. What reaches a person is what's left: the parts that need taste, or that cost too much to get wrong.
Everything irreversible stays with the principal: money going out, anything signed, anything said to someone outside the company in our name, anything touching a customer's data. We don't try to automate those away. They're most of the reason there's a company here rather than a script.
What we're building now runs this way from day one rather than being automated later, which means deciding what the kinds are before there's any volume to review at all. Doing it in that order is slower, and it's the only version that holds up later. We announce new ventures when they're ready.
What it comes down to
An agent-first business isn't fewer people doing more. It's a business arranged on purpose so that the human hours go to kinds rather than individual results, to judgment rather than checking, and to the small set of actions that genuinely can't be undone. Everything else is either checked by a program or cheap enough to get wrong.
Do it the other way round, with agents everywhere and a person reviewing every result, and you haven't automated a business. You've automated your way into a queue and hired yourself to work through it.